Probability & Statistic in Machine Learning(I)
- Published time
What is probability?#
Ex: If there are ten child, three of them know how to play soccer. Find the probability that a child picked at randoms play soccer.
Ans:
Complement of Probability#
According to the previous example. Fine the probability of child NOT playing soccer.
Ans:
Sum of Probability#
Consider the joint event. Kids can play as many sports as they want. What is the probability that childs play soccer or basketball?
Ans:
Independence#
Product Rule
Condition Probability#
Product Rule
Bayes Theoram#
Monty hall problem#
Define the events:
- 𝐸1 = the car is behind door 1
- 𝐸2 = the car is behind door 2
- 𝐸3 = the car is behind door 3
Or, in a more concise way: 𝐸𝑖 = the car is behind door 𝑖 for 𝑖=1,2,3.
Note that these events are mutually exclusive, in other words, you cannot have a car simuntaneously in two doors, because of the rules of the game. This means that,
𝑃(𝐸1 ∩ 𝐸2)=0, 𝑃(𝐸1 ∩ 𝐸3)=0 and 𝑃(𝐸2 ∩ 𝐸3) = 0.
You can say it also by writing that 𝑃(𝐸𝑖 ∩ 𝐸𝑗) = 0 for 𝑖≠𝑗.
Another fact, due to the rules of the game, is that the car is behind one of the three doors, so 𝑃(𝐸1 ∪ 𝐸2 ∪ 𝐸3)=1.
This is, in fact, the sample space, or universe, Ω, because it is the set of all possible outcomes.
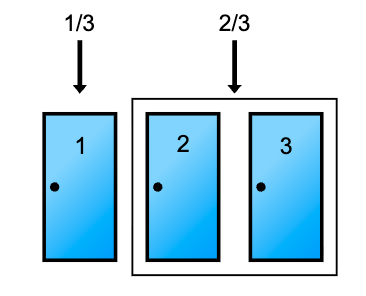
Let's suppose you've chosen door number 1. Since there is an equal chance of the car being behind one of the three doors, we know that 𝑃(𝐸1) = 1/3.
By the complement rule, we know that 𝑃(𝐸𝑐1) = 1−𝑃(𝐸1) = 1−1/3 = 2/3
Since the universe is given by 𝐸1∪𝐸2∪𝐸3 (the car is behind door 1 OR door 2 OR door 3), then 𝐸𝑐1 = 𝐸2∪𝐸3, therefore 𝑃(𝐸2∪𝐸3)= 2/3. You can have a visual idea in the image below.
Now that you chose door 1, the Host then opens door 3, revealing a goat and asks you if you want to switch doors. If you don't switch, the probability of winning remains 13 because this is your initial choice. If you do switch, then, you can notice that the Host gave you an additional information. They showed to you that door 3 does not have a car, which means that 𝑃(𝐸3)=0.
Now you are mostly done, because as you know, 2/3=𝑃(𝐸2 ∪ 𝐸3)=𝑃(𝐸2)+𝑃(𝐸3)−𝑃(𝐸2 ∩ 𝐸3). You already know that 𝑃(𝐸2 ∩ 𝐸3)=0, because they are mutually exclusive events (the car is behind in only one of the three doors), and the Host gave you a very importante piece of additional information: 𝑃(𝐸3)=0. With this, you can easily conclude that:
𝑃(𝑤𝑖𝑛|𝑠𝑤𝑖𝑡𝑐ℎ)=𝑃(𝐸2)=2/3.
In other words, the probability that the car is behind door 2, given that it is not behind door 3 is 2/3≈0.67 as you have just seen in your simulations!
Consider a more complex situation
Now, the game is:
- There are 𝑛 doors, and you must choose one door.
- Host opens 𝑘 doors and revealing goats.
- You may or may not change your previously chosen door.
The question is: is it always better to switch doors? Will it depend on 𝑘?
To answer this question analyticaly, first define the following events:
- 𝐸𝑖= the car is behind door i. In this case, 𝑖=1,…,𝑛.
Again, the 𝐸𝑖's are independent from each other, because there is only 1 car available.
Note that, since the Host never opens the same door the player chose and also never opens the winning door, there is an upper bound for 𝑘, which is 𝑛−2, so 0≤𝑘≤𝑛−2.
Two facts can be assumed:
- The player chooses door 1
- The host opens doors 2,…,𝑘+1
This is because we can always rename the doors to get this result. For instance, if the player chooses door number 10, we can rename it as door 1 and door 1 will become door 10. This is just to avoid getting too complex on indices notations. In math terminology, it is usually said that we can do this without loss of generality, since it will not affect the final result.
Now that there are 𝑛 doors, the probability that the car is behind door 1 is 1/𝑛, i.e.,
𝑃(𝐸1)=1/𝑛.
By the complement rule, the probability that the car is not behind door 1 is:
𝑃(𝐸𝑐1)=1−𝑃(𝐸1)=1−1/𝑛=𝑛−1/𝑛.
Note that
𝐸𝑐1 = 𝐸2∪𝐸3∪…∪𝐸𝑛.
There is a notation to simplify the right hand side equation above, we can write it as:
This works in the same fashion as a summation symbol, but the opeartion being performed is set union.
So, we know that
Now we can answer the question: What is the probability of winning, given that we switch doors?
Let's take a look on the following image:


If the player switches to a random available door, then they must choose one of the 𝑘+2,𝑘+3,…,𝑛−1,𝑛. Therefore, the probability of picking the car is:
The probability of not picking the car in door 1 (𝑃(𝐸𝑐1)=𝑛−1/𝑛) times the probability of picking the car now, which is 1𝑛−𝑘−1 because this is the number of remaining doors.
So, the final probability is given by
It can be rewriten in the following manner:
And the equality only holds when 𝑘=0. This means that the host does not open any door.
Therefore, it is always better to switch doors. This may sound counterintuitive at first, but think that switching doors you are using the new piece of information that the host gave you, whereas if you choose not to switch, you will be ignoring this new information.
Prior and Posterior#
P(A|B):Posterior
P(A):Prior
P(B|A):Likelihood
Probability in ML#
Example Problem: Face generation
- Generate a group of pixels such that resulting image lools like a human face
- Goal: generate images such P(face | pixels ) is high
Random Variables#
Why random variables?
Random variables allow us to model the whole experiment at once.
Event: A set of outcomes
Random variables: A function mapping outcomes to real numbers
Probability Distribution#
- Binomial Distribution
- Bernoulli Distribution
- Uniform Distribution
- Gussian(Normal) Distribution
- Chi-Squared Distribution
Discrete Probability Distribution#
PMF (Probability Mass Function)#
For a discrete random variable , the PMF is defined as:
Properties of PMF:
1. Non-negativity
2. Normalization (Completeness)
The sum of all probabilities must equal 1:
Proof:
Since must take on one of its possible values, all possible outcomes form the sample space:
These events are mutually exclusive (disjoint), so by the law of total probability:
Continuous Probability Distribution#
PDF (Probability Density Function)#
For a continuous random variable , the PDF is denoted as . Unlike PMF, the PDF does not represent the probability at a point. Instead, it describes the relative likelihood of values.
Key Properties:
1. Non-negativity
2. Normalization (Total Probability)
The total area under the curve equals 1:
Proof:
The probability that takes any value in its range must be 1:
3. Probability over an Interval
For any interval :
CDF (Cumulative Distribution Function)#
The CDF is a universal concept defined for both discrete and continuous random variables:
For Discrete Random Variables:
For Continuous Random Variables:
Properties of CDF:
1. Monotonicity
If , then:
Proof:
If , then the event is a subset of :
2. Boundary Conditions
3. Relationship between CDF and PDF
For a continuous random variable, the PDF is the derivative of the CDF:
Proof:
By the Fundamental Theorem of Calculus:
4. Probability Calculation using CDF
For any interval :
Proof:
Sampling from a Normal Distribution#
Use the CDF as shown in the following illustration:


This inverse-CDF approach works well when is easy to evaluate, but it is not the only way to sample from a distribution. In a later post, we will cover more general sampling methods — such as importance sampling, rejection sampling, and MCMC — which are needed when the target distribution's CDF is hard to invert, or when we only know the PDF up to a normalizing constant.